
Iteration Cycle
One round of asking an AI tool again, or editing what it returned, before the result is usable. In the study the site's briefing article cites, the average fell from 3.8 cycles to 2.0 once people assembled structured context before prompting.
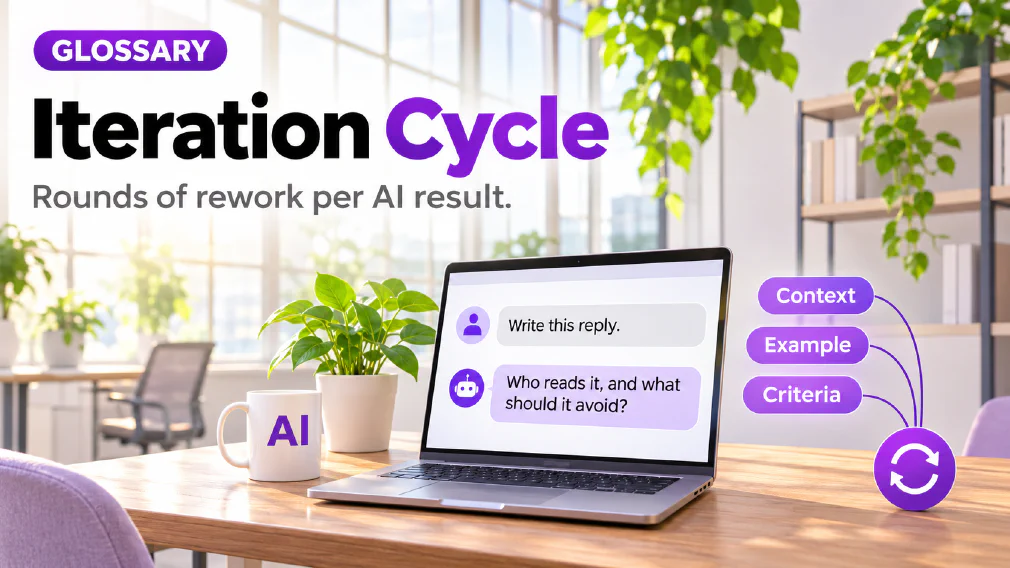
What an iteration cycle is
An iteration cycle is one round of asking an AI tool again, or editing what it returned, before the result is usable. It is easiest to see in the gap between the first answer and the one the person finally sends on. If the first answer needs nothing, there were no extra cycles. If a person asks again for a shorter version, then asks for a warmer tone, then fixes a figure by hand, that is three.
The term counts the person’s rounds, not anything the tool does inside a single response. It is a measure of rework. Each cycle is time spent getting a result from “nearly” to “usable”, and a business that uses AI tools every day pays that time many times over without ever seeing it as one cost.
What the study found
Our briefing article cites a study of 200 documented AI interactions across four tools. It found that when people assembled structured context before prompting, and not after a bad first attempt, the average number of cycles needed to reach a usable result fell from 3.8 to 2.0. First-pass acceptance rose from 32% to 55% in the same data.
The figure this page leans on most is the third one. Incomplete context, not poor wording, was linked to 72% of the iteration cycles in that data. The article’s reading is that the wording was rarely the thing that needed fixing. The people whose results improved did so by changing what surrounded the request, not the request itself.
These are the study’s figures, quoted as the article gives them. They are not the site’s own measurement, and the site has not measured how long a cycle takes or what it costs.
Why most cycles come from missing Context
The briefing article starts from an everyday comparison. Nobody hands a new hire one line, “write the client update”, and expects a usable draft back. They are told who reads it, roughly how long it should run, what last month’s version looked like and what the manager dislikes seeing. A new hire given only the one line would produce the generic, slightly wrong draft that a bare prompt produces from an AI tool.
The tool cannot read the decisions the requester already made in their own head. The person asking for “the client update” knows which client it is, what tone that client expects and what a rejected version looked like. None of that reaches the model unless it is written down. The model can only produce the likely answer to the words it was given.
That is what a generic or slightly wrong answer looks like from the outside. It is not the model inventing something at random. It is the model filling in, plausibly, the part nobody specified. The person then does a second pass that amounts to writing the brief they should have written first, after the fact and one correction at a time. Each correction is a cycle.
Why rewording rarely cuts the number
The instinct, when a result disappoints, is to reword the request. The prompt page describes it: sharper verbs, more specific phrasing, a cleverer instruction. The briefing article argues that this treats a problem of missing context as a problem of language.
A sharper verb changes how an instruction reads. It does not change what the model knows about the audience, the history or the standard the result will be judged against. Two people can type nearly the same clear sentence into the same tool and get very different results, because one of them has built the surrounding habits and the other starts from a blank line every time.
None of this makes wording unimportant. The article is clear that prompt engineering is still real and still useful, in the way that phrasing an instruction to a new hire clearly still matters. A muddled sentence produces a muddled answer whatever surrounds it. The point is about where the extra rounds come from. In the study, they came mostly from what was missing, not from how the request was phrased.
What an extra cycle costs
The plainest cost is time. Each extra cycle is a round of reading the result, working out what is wrong with it and asking again or editing it by hand. Across a team using AI tools every day, that is rework that never shows up as a line anywhere.
There is a second cost that is easier to miss. A result that needed several rounds is more likely to have been shaped by whoever was most persistent, not by a clear standard. The next person, asking for the same thing, starts again and finds their own way to something usable. The knowledge of what a good result looks like stays in the head of whoever got there, which is the situation a written brief is meant to end.
The page does not put a number on either cost, because none of the site’s articles measures one. What the study offers is the count of rounds and the share of them linked to missing context. That is enough to say where the effort is going.
How to cut the number of cycles
The briefing article’s answer is to write the request as a brief before the first attempt, in the way a new hire would be briefed, and not after a bad first answer. It is a change in order, not a change in effort. The same information gets written, but once and up front, instead of in fragments across several rounds of correction.
That is why the study separates context assembled before prompting from context added afterwards. The people whose averages fell did the same thinking as everyone else. They did it at the start.
The six parts of a brief that cut cycles
The article names six parts, each with a new-hire equivalent. A missing part tends to leave a recognisable pattern, and the pattern is usually a cycle.
- Role. What job the AI is doing right now: drafting, summarising or analysing. A role with no goal produces confident work aimed at the wrong reader.
- Goal. The deliverable, who reads it and roughly how long it should be. A goal with no constraints produces something usable that still needs a tone pass.
- Context. What a newcomer would need on day one that nobody thinks to say aloud: the audience, the history, the constraint everyone in the room already knows. Most prompts skip this part, because it feels obvious to the person who already has it.
- Constraints. What to avoid, such as house style, tone or a client who dislikes being sold to. A constraint stated once costs less than the same mistake corrected on every draft.
- Examples. One example of a result you have already accepted. A description of quality is always vaguer than a real instance of it, and constraints without an example can produce something that obeys every rule and still does not read right.
- Success criteria. How the result will be judged, stated before the work starts and not decided afterwards when the draft already exists. A reasonable first draft can be rejected for a reason nobody mentioned in advance, and that rejection is a cycle.
The AI brief page covers the six parts in full. Writing a brief this way takes longer than typing a sentence. The study’s figures describe the trade: more effort first, fewer rounds after.
Keeping the briefs that work
Writing six parts into every request gets tedious, which is why a new hire’s induction is written down once and not repeated from memory every morning. The article gives two ways to do the same.
The first is custom instructions, which carry the standing half of the context into every request. A person then briefs only what is new for this task. The second is a prompt library: briefs that already cleared the bar once, kept and reused and not rewritten from scratch. Both turn briefing from something a person has to remember into something a person can open.
This also changes how a cycle should be read. A cycle that was needed to get a result right is information about what the brief was missing. The useful move is to put that missing part into the brief that gets kept, so the next request does not need the round.
Why it is a team habit
The briefing article treats this as a habit for a team and not a wording skill for one person. A person who has learned to write good prompts carries that skill to their next tool and their next job. The rest of the team does not inherit it, and the same missing-context problem shows up with the next hire, the next tool or the next task nobody has briefed properly.
A team trained to assemble a brief, and handed a shared starting set of briefs that work, keeps the standard when the tool underneath changes. The skill that survives a change of tool is the briefing habit, not the phrasing that happened to work last month. That is the argument for treating the number of cycles as something a team works on together. The upskilling page covers how a team builds a skill of that kind.
A worked example
An illustration, not a case study. A manager asks an AI tool for the weekly client update and types one line: “Write the client update.”
The first answer is long and formal. The manager asks for a shorter version. The second answer is shorter, but the tone is cold, so the manager asks for something warmer. The third answer is warm, but it does not mention the delay the client already knows about, so the manager types the missing sentence in by hand. That is three cycles, and the result is usable.
Now the same request as a brief. It names the client’s reader and how long the update should run. It attaches last month’s accepted update as the example. It says to avoid sales language and to mention the delay. It says the update will be judged on whether the client can read it on a phone in a minute. The first answer is far closer. Each of the three corrections was something the brief would have said once, before the first attempt.
The illustration carries no figures on purpose. It shows where the rounds come from, which is the point of the study’s 72%.
What the figures do not show
Two limits are worth stating, and both come from the AI brief page. The study is 200 interactions, so it describes a pattern and does not guarantee a result for any one business. And the figures are about acceptance and iteration, not about accuracy.
The second limit matters most in practice. A well-briefed answer reaches the person in fewer rounds, and the person may accept it sooner, but a mistake in it is still a mistake. The average also fell to 2.0, not to zero, so some rounds remain even with a good brief. A person still needs to check the result before it goes anywhere that matters, which is the job described on the human in the loop page.
Mix-ups worth avoiding
Four confusions come up often enough to name. The first is treating rewording as the cure, when the study linked most cycles to missing context. The second is reading a lower cycle count as a more accurate result, when the figures describe acceptance and not accuracy. The third is blaming the tool for a generic answer, when the answer is often the tool filling in what nobody specified, which is also how a hallucination can look from outside. The fourth is confusing it with the team briefing, which is a meeting that prepares people for training, a different thing from briefing an AI tool.
How we use it
The briefing article’s advice is the one we pass on: keep the briefs that work, through custom instructions that carry standing context or a prompt library of briefs that already cleared the bar once. It treats this as a team habit and not one person’s skill, because a team trained to assemble a brief keeps the standard when the tool changes.
If you would like to talk through where your own team’s rounds of rework come from, a discovery call is a quick way to start.
Sources
- How to brief an AI tool like you’d brief a new hire: the study of 200 AI interactions across four tools, the 3.8 to 2.0 cycles, the 32% to 55% first-pass acceptance, the 72% linked to incomplete context, the new-hire comparison, the six parts of a brief, and keeping the briefs that work as a team habit.
- Prompt: most extra rounds of editing linked to missing context, and rewording as the instinct that treats a context problem as a language problem.
- AI brief: the figures describing acceptance and iteration and not accuracy, and the study describing a pattern and not a guarantee.
- Prompt engineering: context engineering sitting alongside prompt engineering and not replacing it.
- Custom instructions, Prompt library, Human in the loop, Hallucination, Team briefing and Upskilling: the neighbouring terms this page links to.
FAQ
Questions about Iteration Cycle
Why does an AI Tool need several attempts to get a result Right?
Usually because the request was missing context, not because it was badly worded. The briefing article cites a study of 200 AI interactions across four tools in which incomplete context was linked to 72% of iteration cycles. Rewording changes how an instruction reads, not what the model knows about the audience, the history or the standard.
How can a team cut the number of iteration cycles?
Write the request as a brief before the first attempt, not after a bad one. The briefing article names six parts: the role, the deliverable and its reader, the background, what to avoid, one accepted example and how the result is judged. In the study it cites, first-pass acceptance rose from 32% to 55% once people assembled structured context first.
What counts as one iteration cycle?
One round of asking an AI tool again, or editing what it returned, before the result is usable. A second prompt that fixes the tone is one cycle. A round of editing by hand is one cycle. The count ends when the result is good enough to use, so a result accepted on the first attempt took no extra cycles.
What did the study find about iteration cycles?
The briefing article cites a study of 200 documented AI interactions across four tools. When people assembled structured context before prompting, the average number of cycles fell from 3.8 to 2.0, and first-pass acceptance rose from 32% to 55%. Incomplete context was linked to 72% of the cycles. These are the study's figures, not the site's own measurement.
Does a lower cycle count mean the output is correct?
No. The figures describe acceptance and iteration, not accuracy. A well-briefed result can reach the person in fewer rounds and still contain a mistake, so it still needs checking. The human in the loop page covers that check.
Does rewording the Prompt cut the number of rounds?
Rarely on its own. The briefing article says a sharper verb changes how the instruction reads, not what the model knows about the audience, the history or the standard the result will be judged against. Clear wording still matters, but the study linked most extra rounds to missing context, not to wording.
Can Custom Instructions or a Prompt Library cut the rounds?
The briefing article presents both as ways to keep the briefs that work. Custom instructions carry the standing half of the context into every request, so a person only briefs what is new. A prompt library holds briefs that already cleared the bar once, so nobody rewrites them from scratch each time.
Is cutting rounds a Personal skill or a team habit?
The briefing article treats it as a team habit. A person who has learned to brief well carries the skill to their next tool, but the rest of the team does not inherit it. A team trained to assemble a brief, with a shared set of briefs that work, keeps the standard when the tool underneath changes.
How to brief an AI Tool like you'd brief a New hireUpskilling
What it means for a Business
Each extra cycle is time spent on rework. The briefing article reports that incomplete context, not poor wording, was linked to 72% of the iteration cycles in that study, so the fix is a fuller brief rather than a reworded prompt.
Ready to Put This to Work?
Tell us where your team is with AI and we will tell you honestly what would make the biggest difference.